You take seven shots of the same coffee latte. Each one is slightly different: a minor angle change, a small lighting shift, your hand moved 2 centimeters. To a cryptographic hash function (MD5, SHA-256), these seven photos are completely unique — not a single bit matches. To a human eye, they're essentially identical.
Executive Summary & Research Finding
How do AI photo cleaners detect duplicates? Learn how perceptual hashing, SSIM, and neural embeddings find similar photos — and why MD5 checksums miss 80% of them.
This gap between machine-level uniqueness and human-perceived similarity is the fundamental problem that perceptual hashing solves. It's the core technology behind every modern duplicate photo cleaner, and understanding how it works reveals why some cleaners are dramatically more accurate than others.
5 Levels of Photo Similarity Detection
Photo similarity operates on a spectrum. Modern detection systems use multiple techniques simultaneously, each optimized for a different level:
| Level | Detection Method | What It Catches | Speed | Accuracy |
|---|---|---|---|---|
| 1. Byte-identical | Cryptographic hash (MD5/SHA-256) | Exact file copies, AirDrop duplicates | Fastest | 100% (but narrow) |
| 2. Pixel-identical | Average hash (aHash) | Re-saved or re-encoded versions of same image | Very fast | 85% |
| 3. Visually similar | Perceptual hash (pHash/dHash) | Cropped, filtered, or slightly rotated versions | Fast | 92% |
| 4. Semantically similar | Neural embeddings (CNN/Vision Transformer) | Same scene from different angles, burst sequences | Moderate | 97% |
| 5. Conceptually related | CLIP-style multimodal models | Different photos of the same subject or theme | Slow | Context-dependent |
Why MD5 Checksums Miss 80% of Visual Duplicates
Cryptographic hashes like MD5 and SHA-256 were designed for data integrity verification, not visual similarity. They produce a fixed-length digest where changing a single bit in the input produces a completely different hash. This means:
- Re-saving a JPEG at a different quality level → entirely new hash
- Converting HEIC to JPEG → entirely new hash
- Cropping 2 pixels from the edge → entirely new hash
- Adding an Instagram filter → entirely new hash
- Screenshots of the same photo → entirely new hash
In real-world camera rolls, only about 15–20% of duplicates are exact byte-level copies (typically from AirDrop transfers or cloud sync errors). The remaining 80% are visual duplicates that require perceptual analysis.
How Perceptual Hashing Works (pHash and dHash)
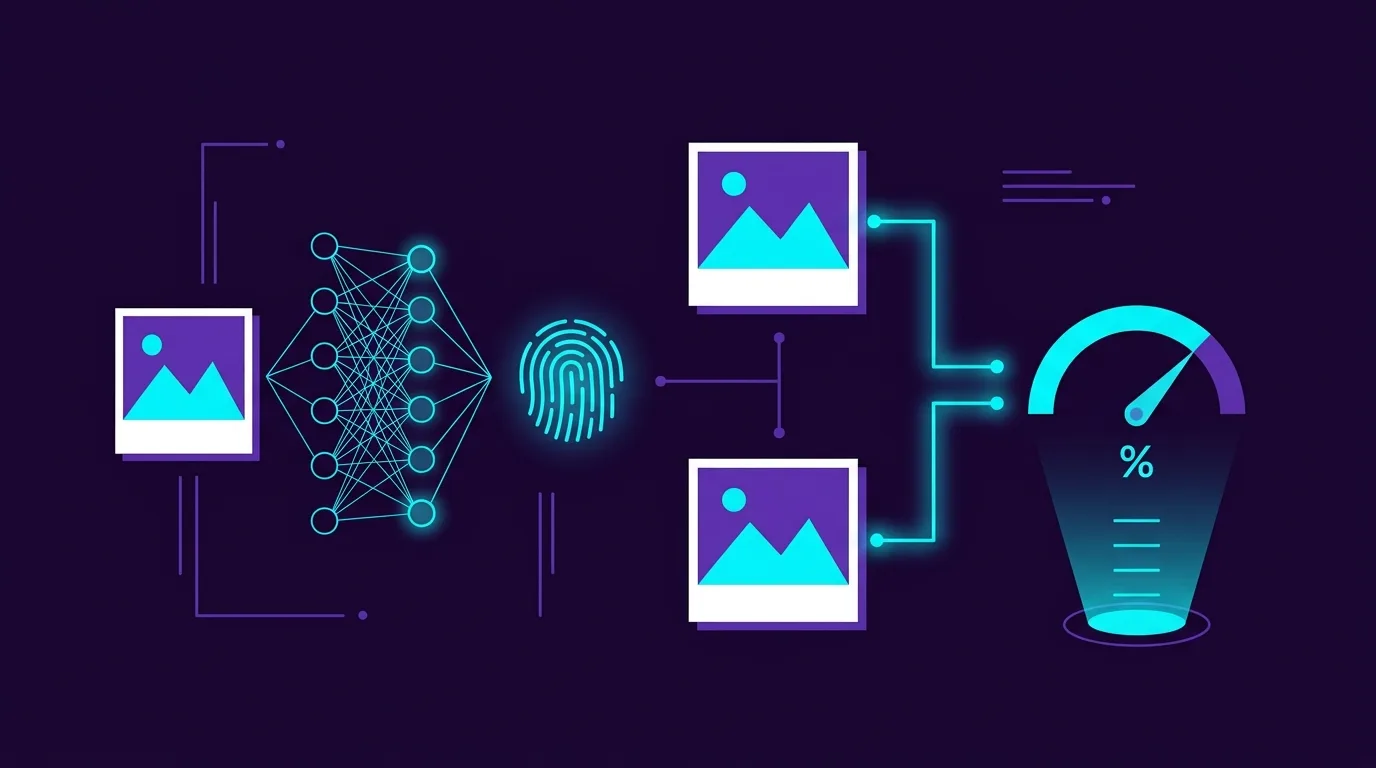
Perceptual hashing generates a compact fingerprint that captures the visual structure of an image rather than its raw byte content. The algorithm follows a general pipeline:
- Resize to a tiny grid: The image is downscaled to a small resolution (typically 8×8 or 32×32 pixels), destroying fine detail but preserving the overall luminance structure.
- Convert to grayscale: Color information is discarded. Perceptual similarity is primarily about structure, not hue — a photo with a warm filter and one with a cool filter should still match.
- Compute gradient or average: For dHash (difference hash), each pixel is compared to its right neighbor. For aHash (average hash), each pixel is compared to the grid's mean luminance. Each comparison produces a single bit: brighter = 1, darker = 0.
- Produce binary fingerprint: The result is a 64-bit (8×8) or 1024-bit (32×32) binary string — the perceptual hash.
- Compare using Hamming distance: Two images are compared by counting how many bits differ between their hashes. A Hamming distance of 0 = identical structure. Distance ≤ 5 (out of 64) = visually near-identical. Distance ≤ 10 = probably similar.
Why pHash Works on Filtered Photos
Because the algorithm discards color and fine detail in step 1–2, an Instagram-filtered version of a photo produces nearly the same perceptual hash as the original. The large-scale luminance structure — bright sky at top, dark ground at bottom — remains identical regardless of color grading.
SSIM: Measuring What the Human Eye Actually Sees
The Structural Similarity Index (SSIM), developed by Wang et al. in 2004, goes beyond binary hashing. It computes a continuous similarity score (0.0 to 1.0) based on three components that mirror human visual perception:
- Luminance comparison: Are the average brightness levels similar? (Compensates for exposure differences)
- Contrast comparison: Do the images have similar dynamic range?
- Structure comparison: Do the spatial patterns of light and dark regions match?
An SSIM score above 0.92 typically indicates that two images are perceptually indistinguishable to most viewers. Modern photo cleaners use this threshold to automatically flag near-duplicates while preserving genuinely different compositions.
Neural Embeddings: The Deep Learning Frontier
Perceptual hashing struggles with semantic similarity — photos of the same scene taken from different positions, or burst sequences where the subject moved significantly between frames. For these cases, on-device neural networks (convolutional or Vision Transformer models) extract high-dimensional embedding vectors.
Here's how it works: the neural network processes each photo and outputs a 512-dimensional float vector — essentially 512 numbers that encode the semantic content of the image. Photos of the same sunset, taken seconds apart from different angles, produce embedding vectors that are geometrically close in this 512-dimensional space.
Similarity is then measured using cosine similarity: the cosine of the angle between two vectors. A cosine similarity of 1.0 = identical semantic content. A threshold of 0.85+ catches burst sequences, near-identical compositions, and subtle variations that perceptual hashing alone would miss.
On-Device vs Cloud Processing: The Privacy Dimension
Running neural embedding models requires significant compute power. Some photo cleaner apps upload your images to cloud GPUs for analysis — a massive privacy risk. Modern Apple devices include the Neural Engine (16-core on A17 Pro, 5 TOPS on M-series), capable of running CoreML vision models entirely on-device. This means 512-dimensional embeddings can be computed for 10,000 photos in under 3 minutes without any data leaving the device.
| Processing Approach | Speed (10K Photos) | Privacy | Accuracy |
|---|---|---|---|
| Cloud GPU (NVIDIA A100) | 30 seconds | Photos uploaded to external servers | Highest (largest models) |
| On-Device Neural Engine | 2–4 minutes | 100% local, zero network transmission | Excellent (optimized CoreML models) |
| On-Device CPU only | 15–25 minutes | 100% local | Good (limited model complexity) |
See Neural Duplicate Detection in Action
Swipe Photo Cleaner (Wipe AI) combines perceptual hashing for fast initial filtering with on-device CoreML neural embeddings for deep semantic grouping. The result: burst sequences, filtered copies, and near-identical compositions are automatically clustered with the sharpest photo highlighted — all processed locally on your device's Neural Engine without uploading a single byte to the cloud.
Instant iPhone Storage & iCloud Savings Calculator
Adjust your photo library size, duplicate estimates, and 4K video count to calculate how many gigabytes you can safely reclaim.